Research
Benchmarks, papers, releases, and other lab updates — one place to track how the frontier moves.
-
 Benchmarks
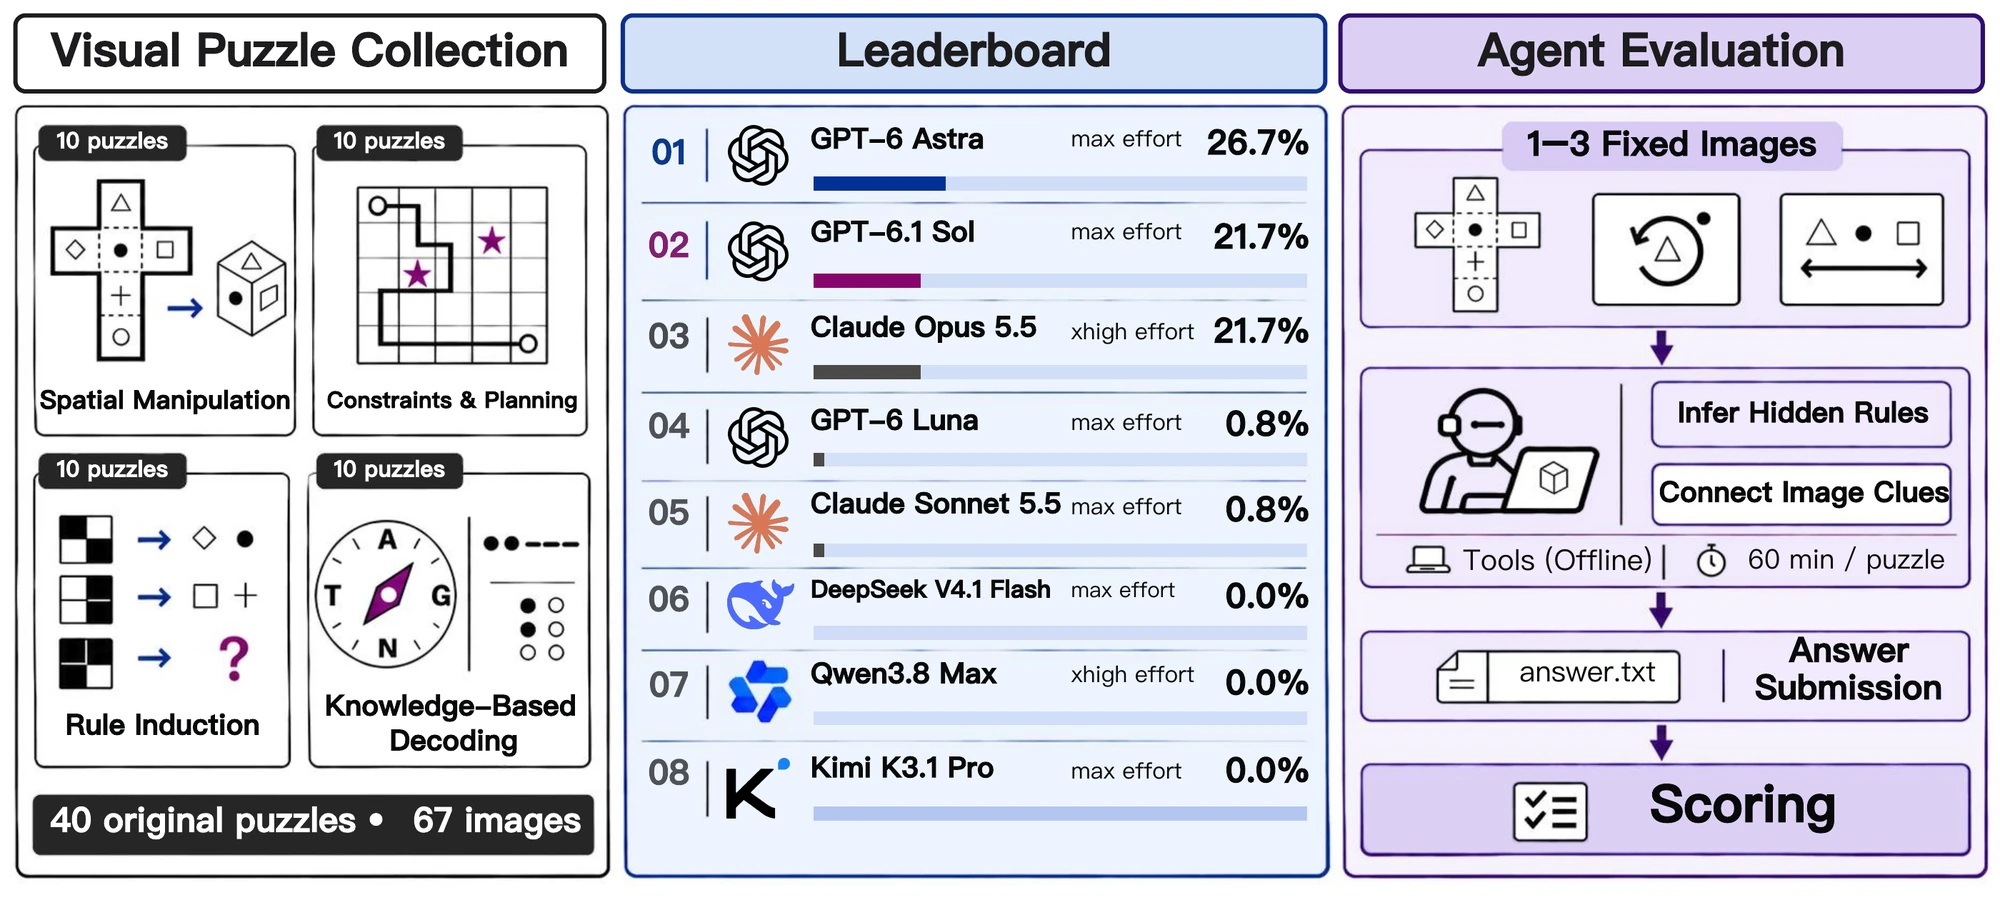
Visual Cipher Bench
Can coding agents discover the rules hidden in images? On 40 original visual puzzles, the best model solves 26.7%.
-
 Benchmarks
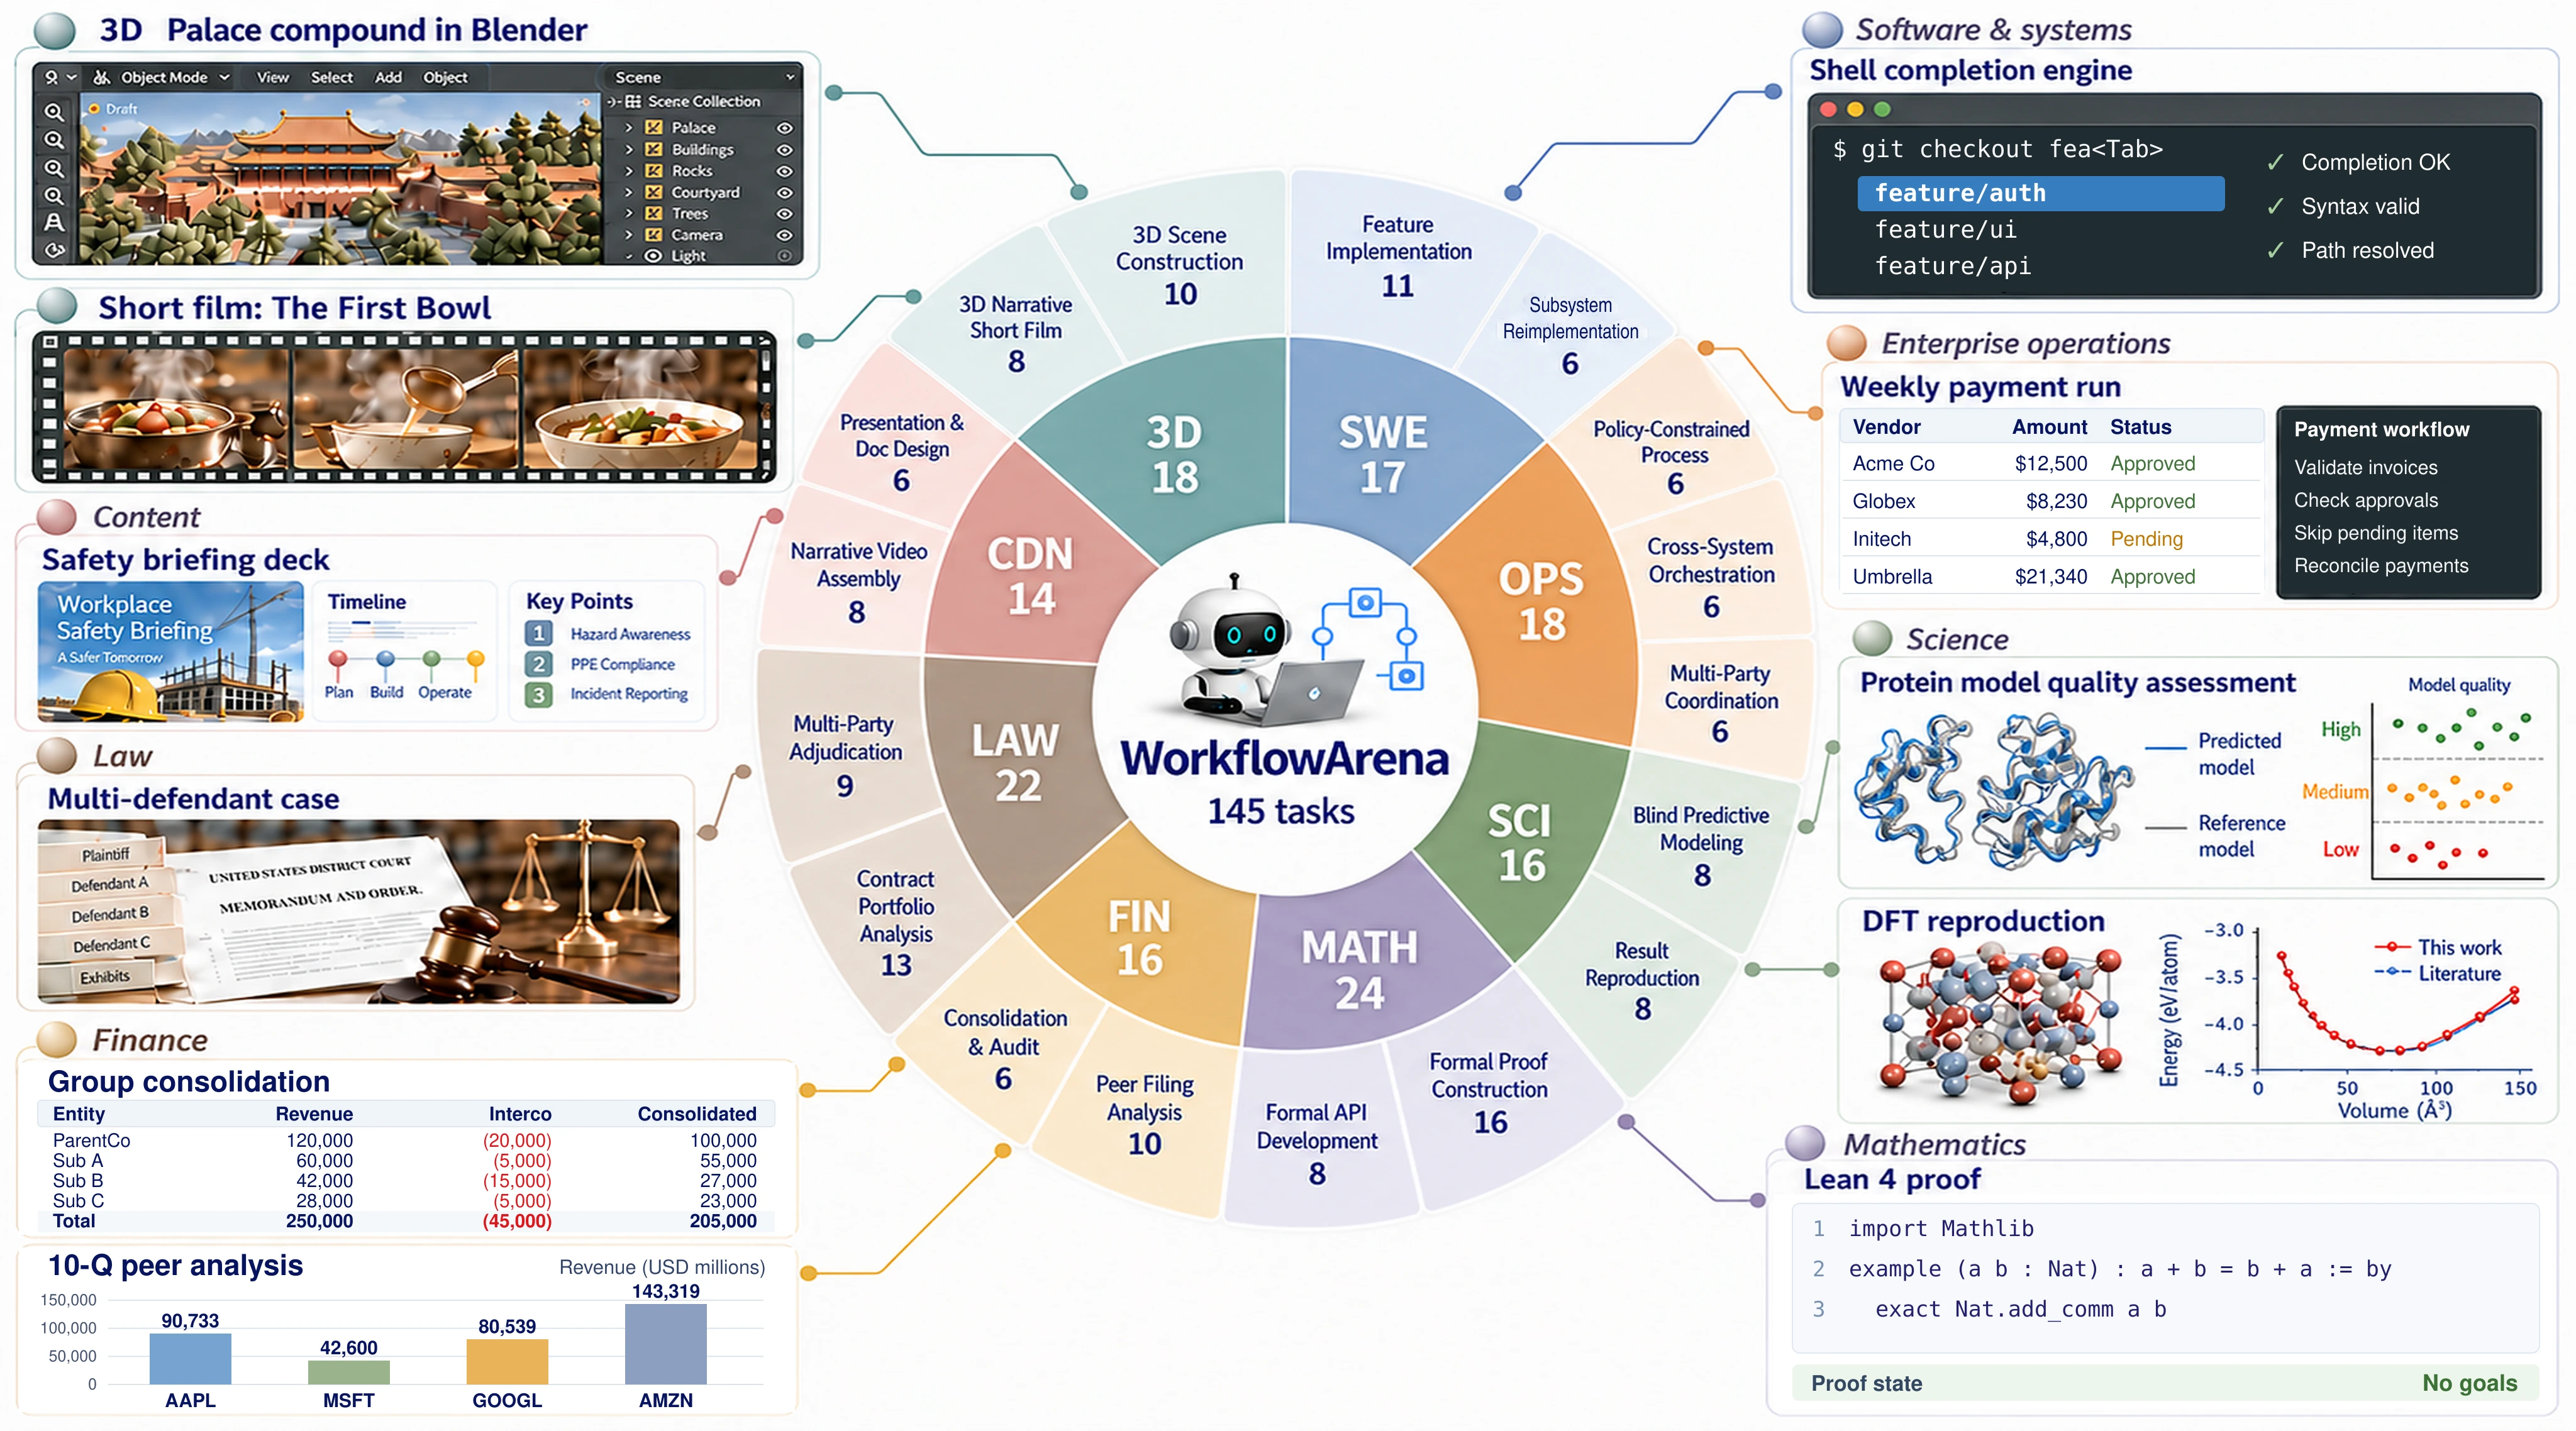
WorkflowArena
Benchmarking how LLM-based multi-agent systems divide work, coordinate workers, and revise workflows across 145 long-horizon tasks in eight domains.
-
 Benchmarks
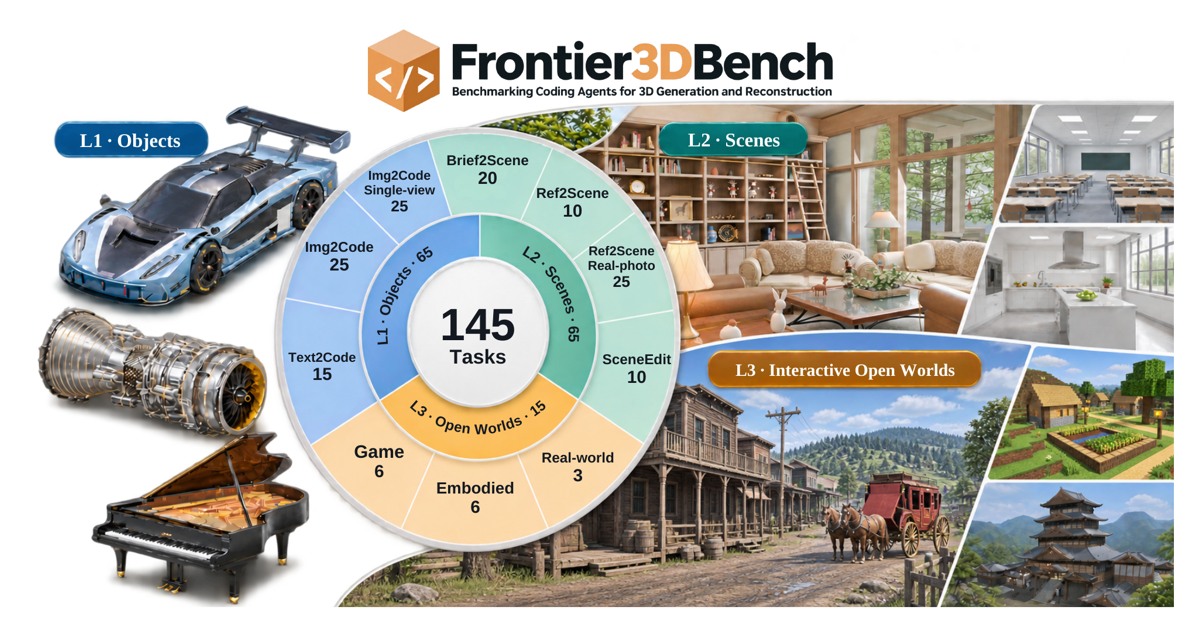
Frontier3DBench
Benchmarking coding agents across 3D objects, scenes, and interactive open worlds, with editable Blender and Unreal Engine assets.
-
 Benchmarks
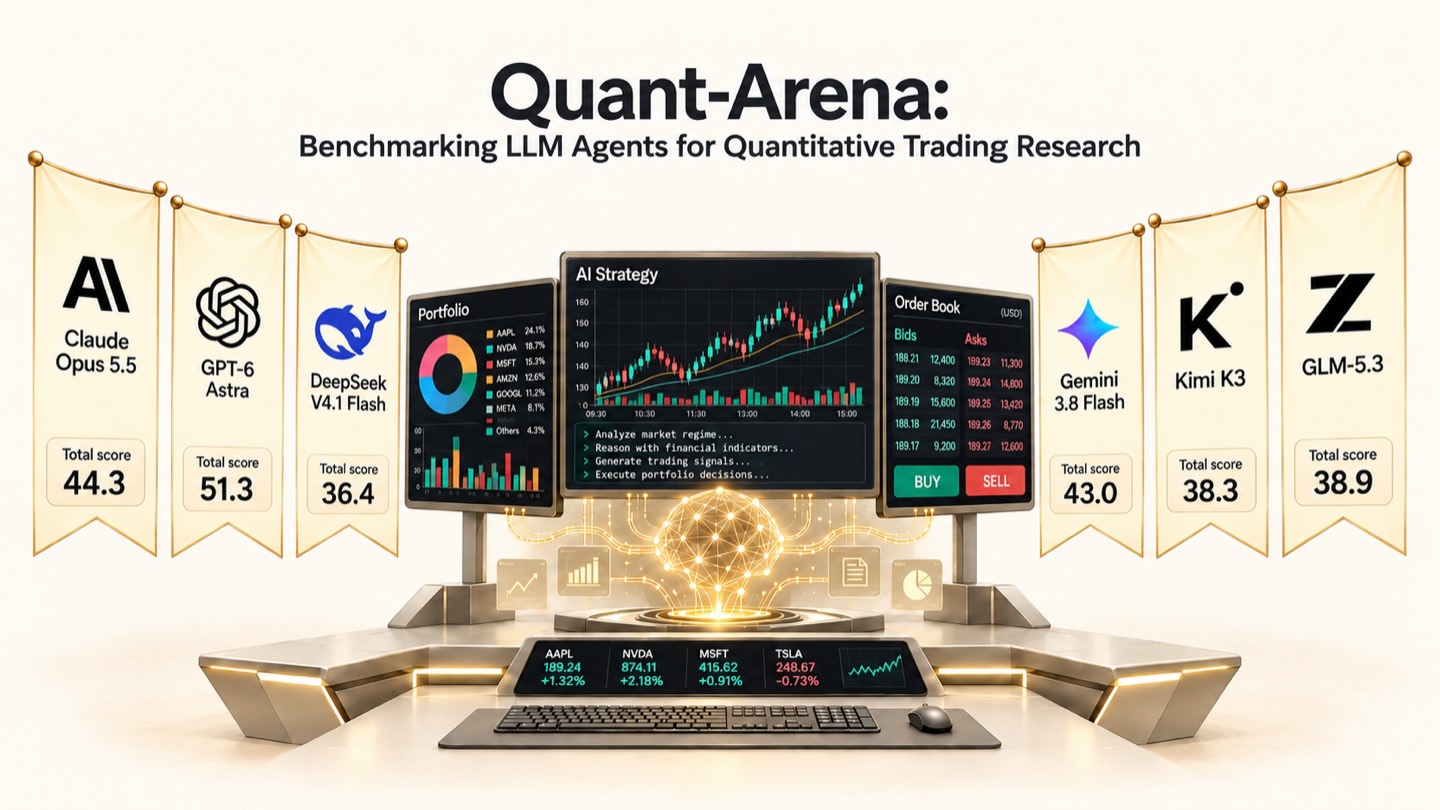
Quant-Arena: Benchmarking LLM Agents for Quantitative Trading Research
A benchmark for quantitative research with LLMs: each model researches on 2022–2023 with bounded feedback, commits one strategy, and is assessed once on a sealed 2024 window in a cash account.
-
 Research Preview
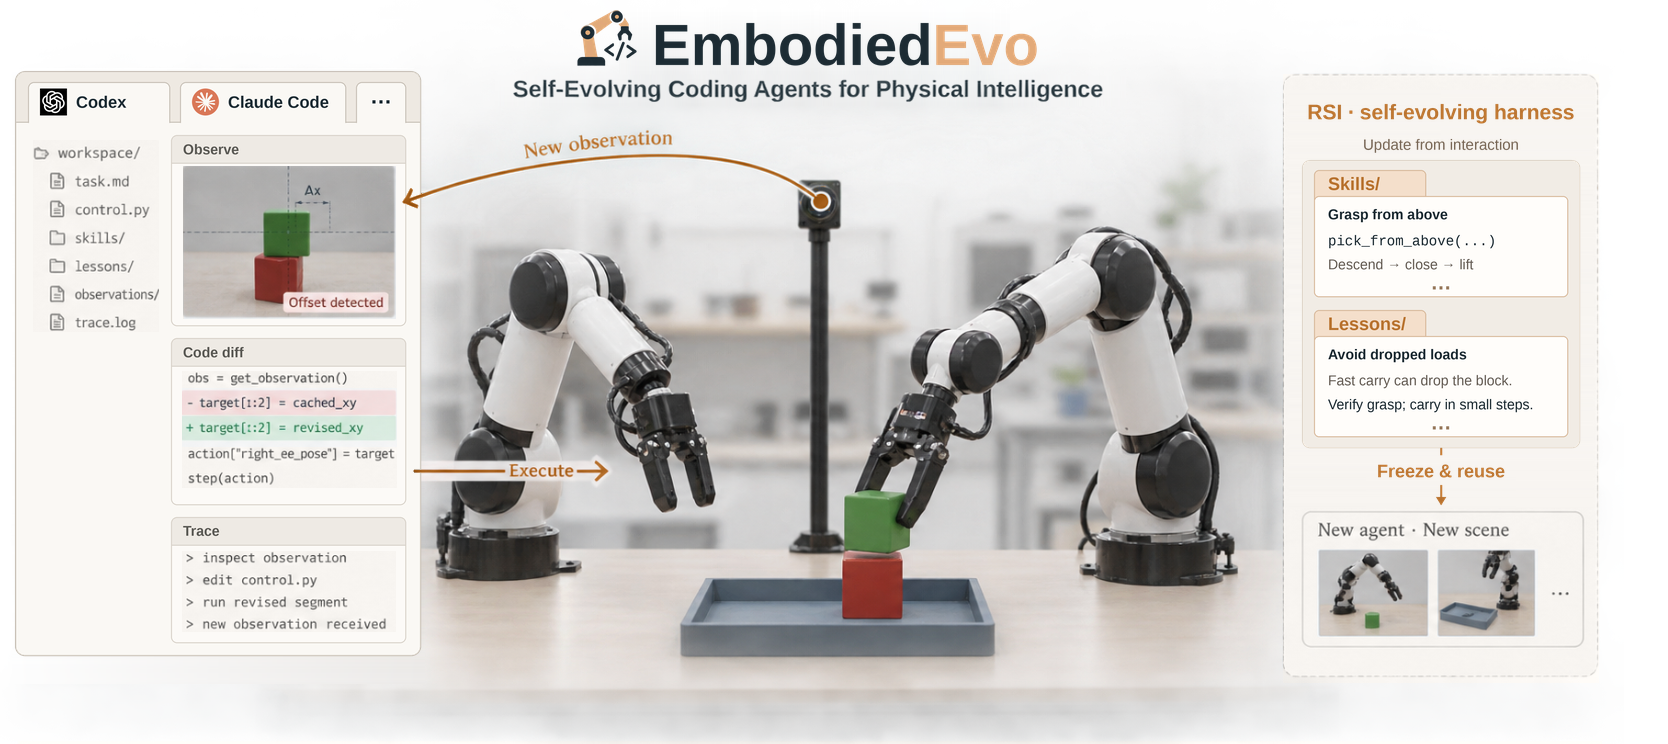
EmbodiedEvo: Self-Evolving Coding Agent For Physical Intelligence
Coding agents learn from physical interaction, retain reusable Skills and Lessons, and pass that experience to fresh agents.
-
 Research Preview
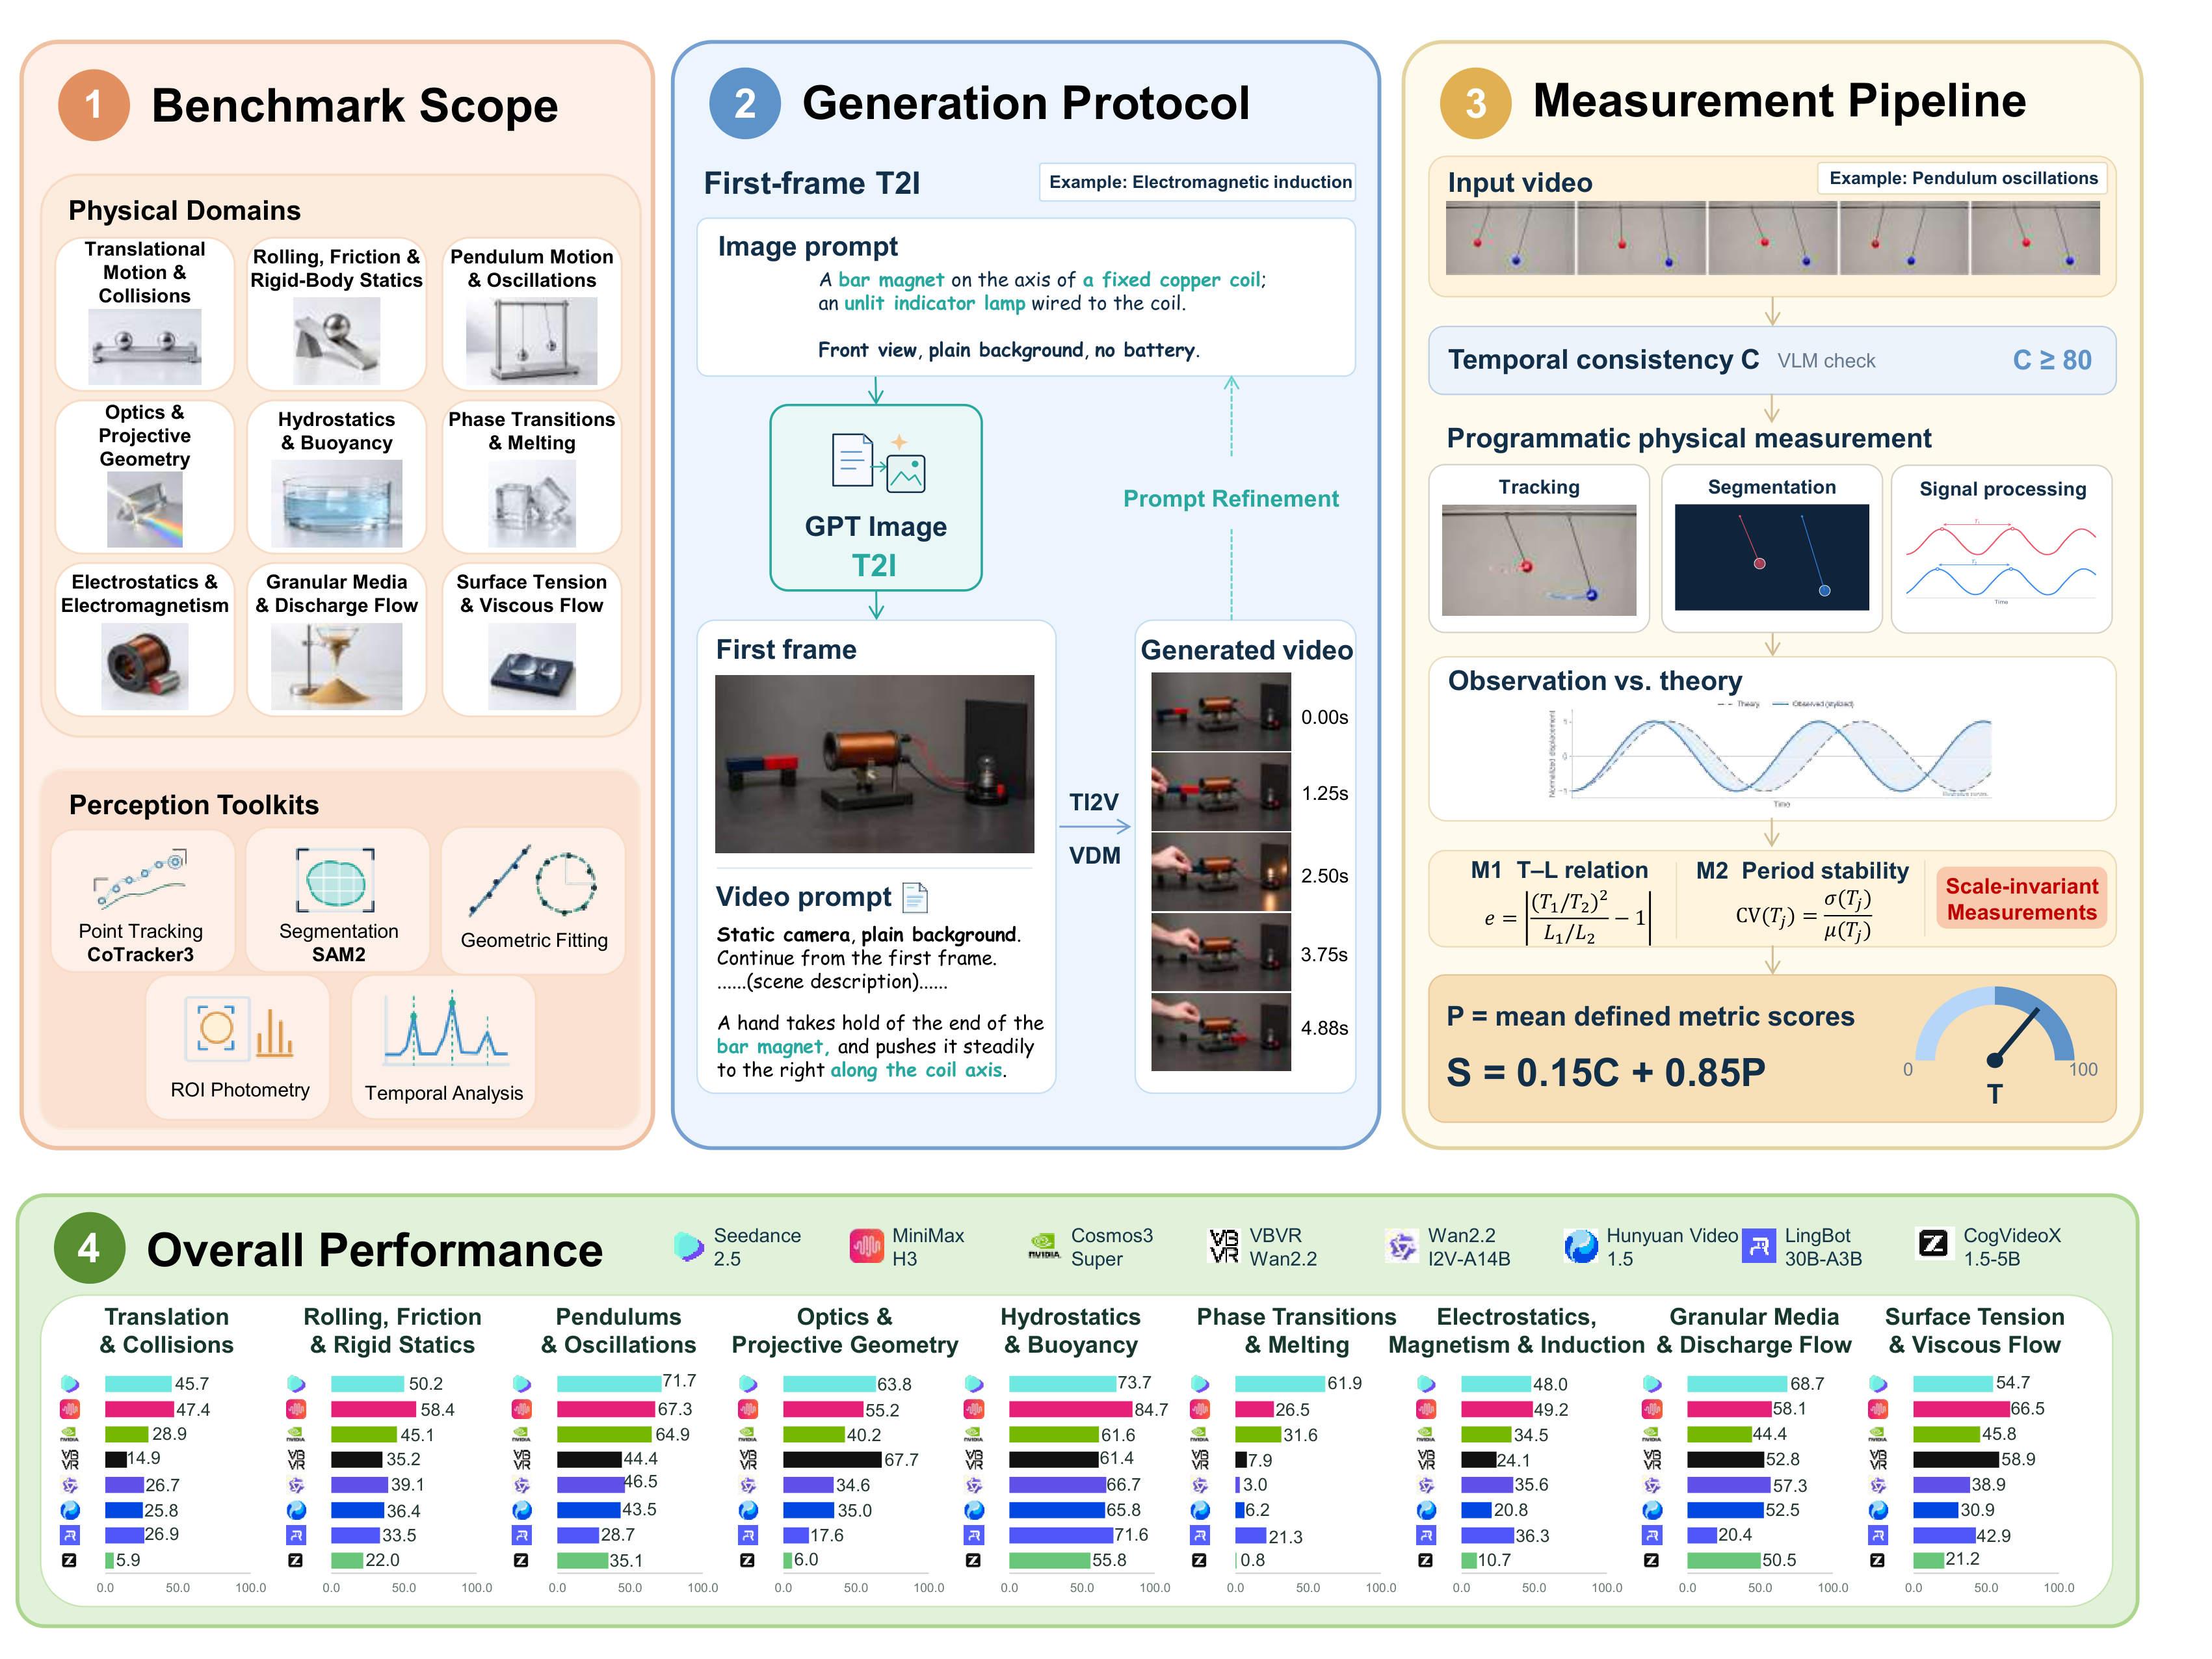
World Models’ Last Exam in Physics
Compare eight video models across 40 physical tasks and nine categories, with side-by-side measurement visualizations.
-
 Benchmarks
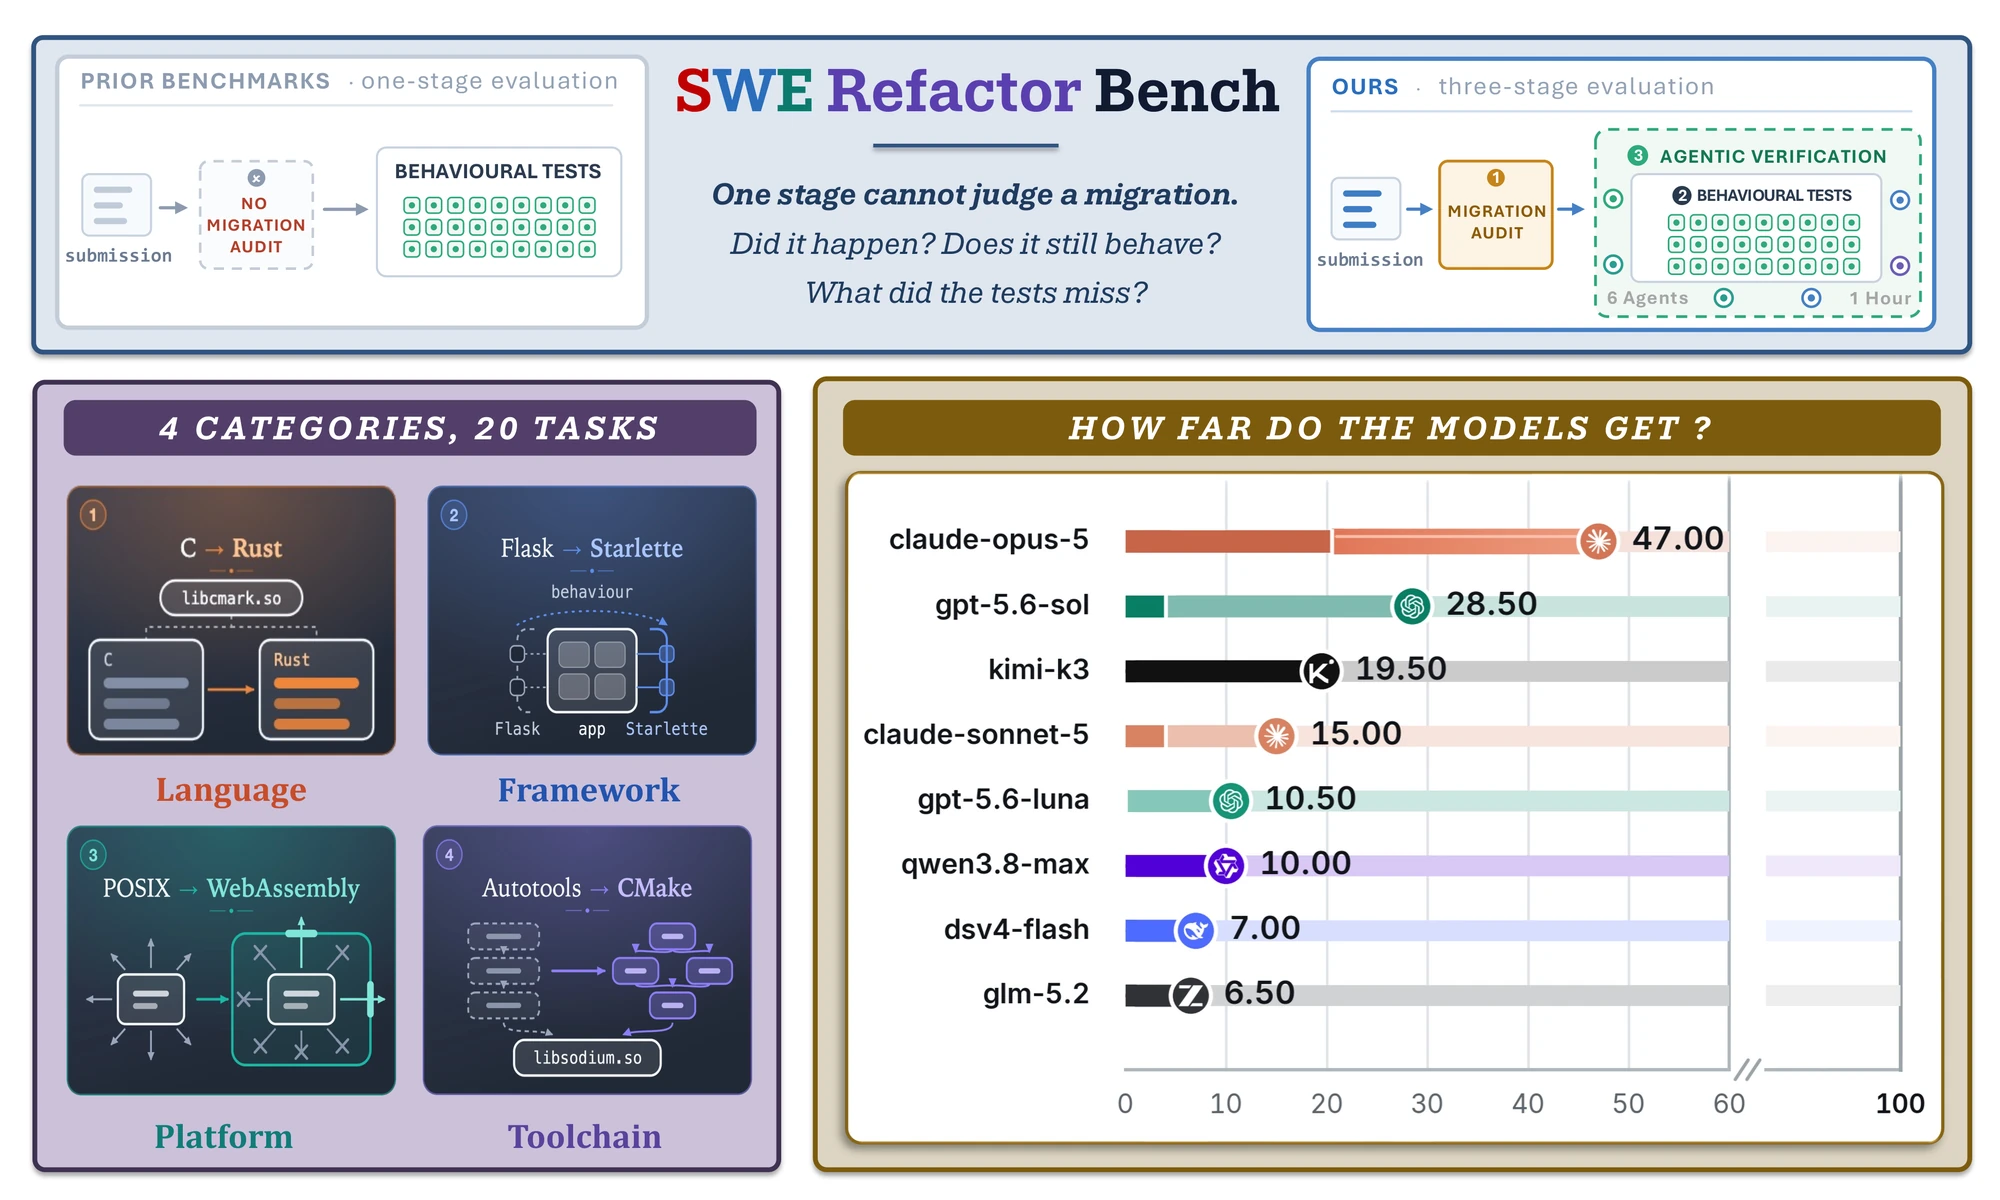
SWE Refactor Bench
Move a whole repository to another stack — language, framework, platform or build system — and change nothing about what it does. A migration starts with its tests already green, so passing them proves nothing: 20 real repositories graded by whether the old stack is gone, whether every recorded behaviour survived, and what six adversarial coding agents can still break.
-
 Benchmark
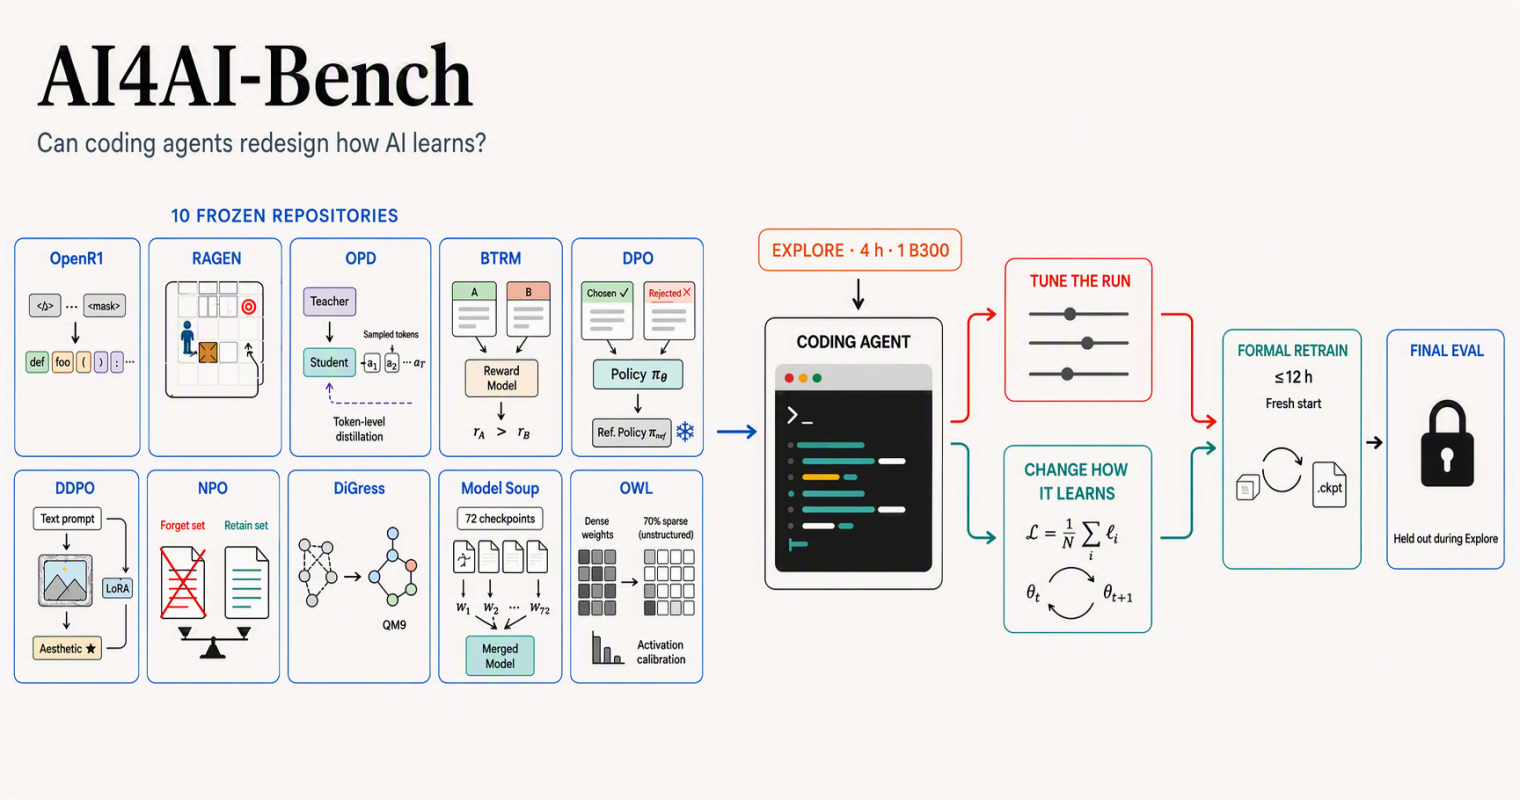
AI4AI-Bench
Give a coding agent a real research codebase and four hours to improve how it trains a model. Most tune the settings around the existing method; few rewrite the method itself.
-
 Open source
OpenChronicle
An open, local-first memory layer for LLM agents. OpenChronicle captures structured context from your screen and apps into inspectable Markdown memory — projects, tools, people, decisions — that any tool-calling agent can read, run locally, and share across models.
-
 Benchmarks
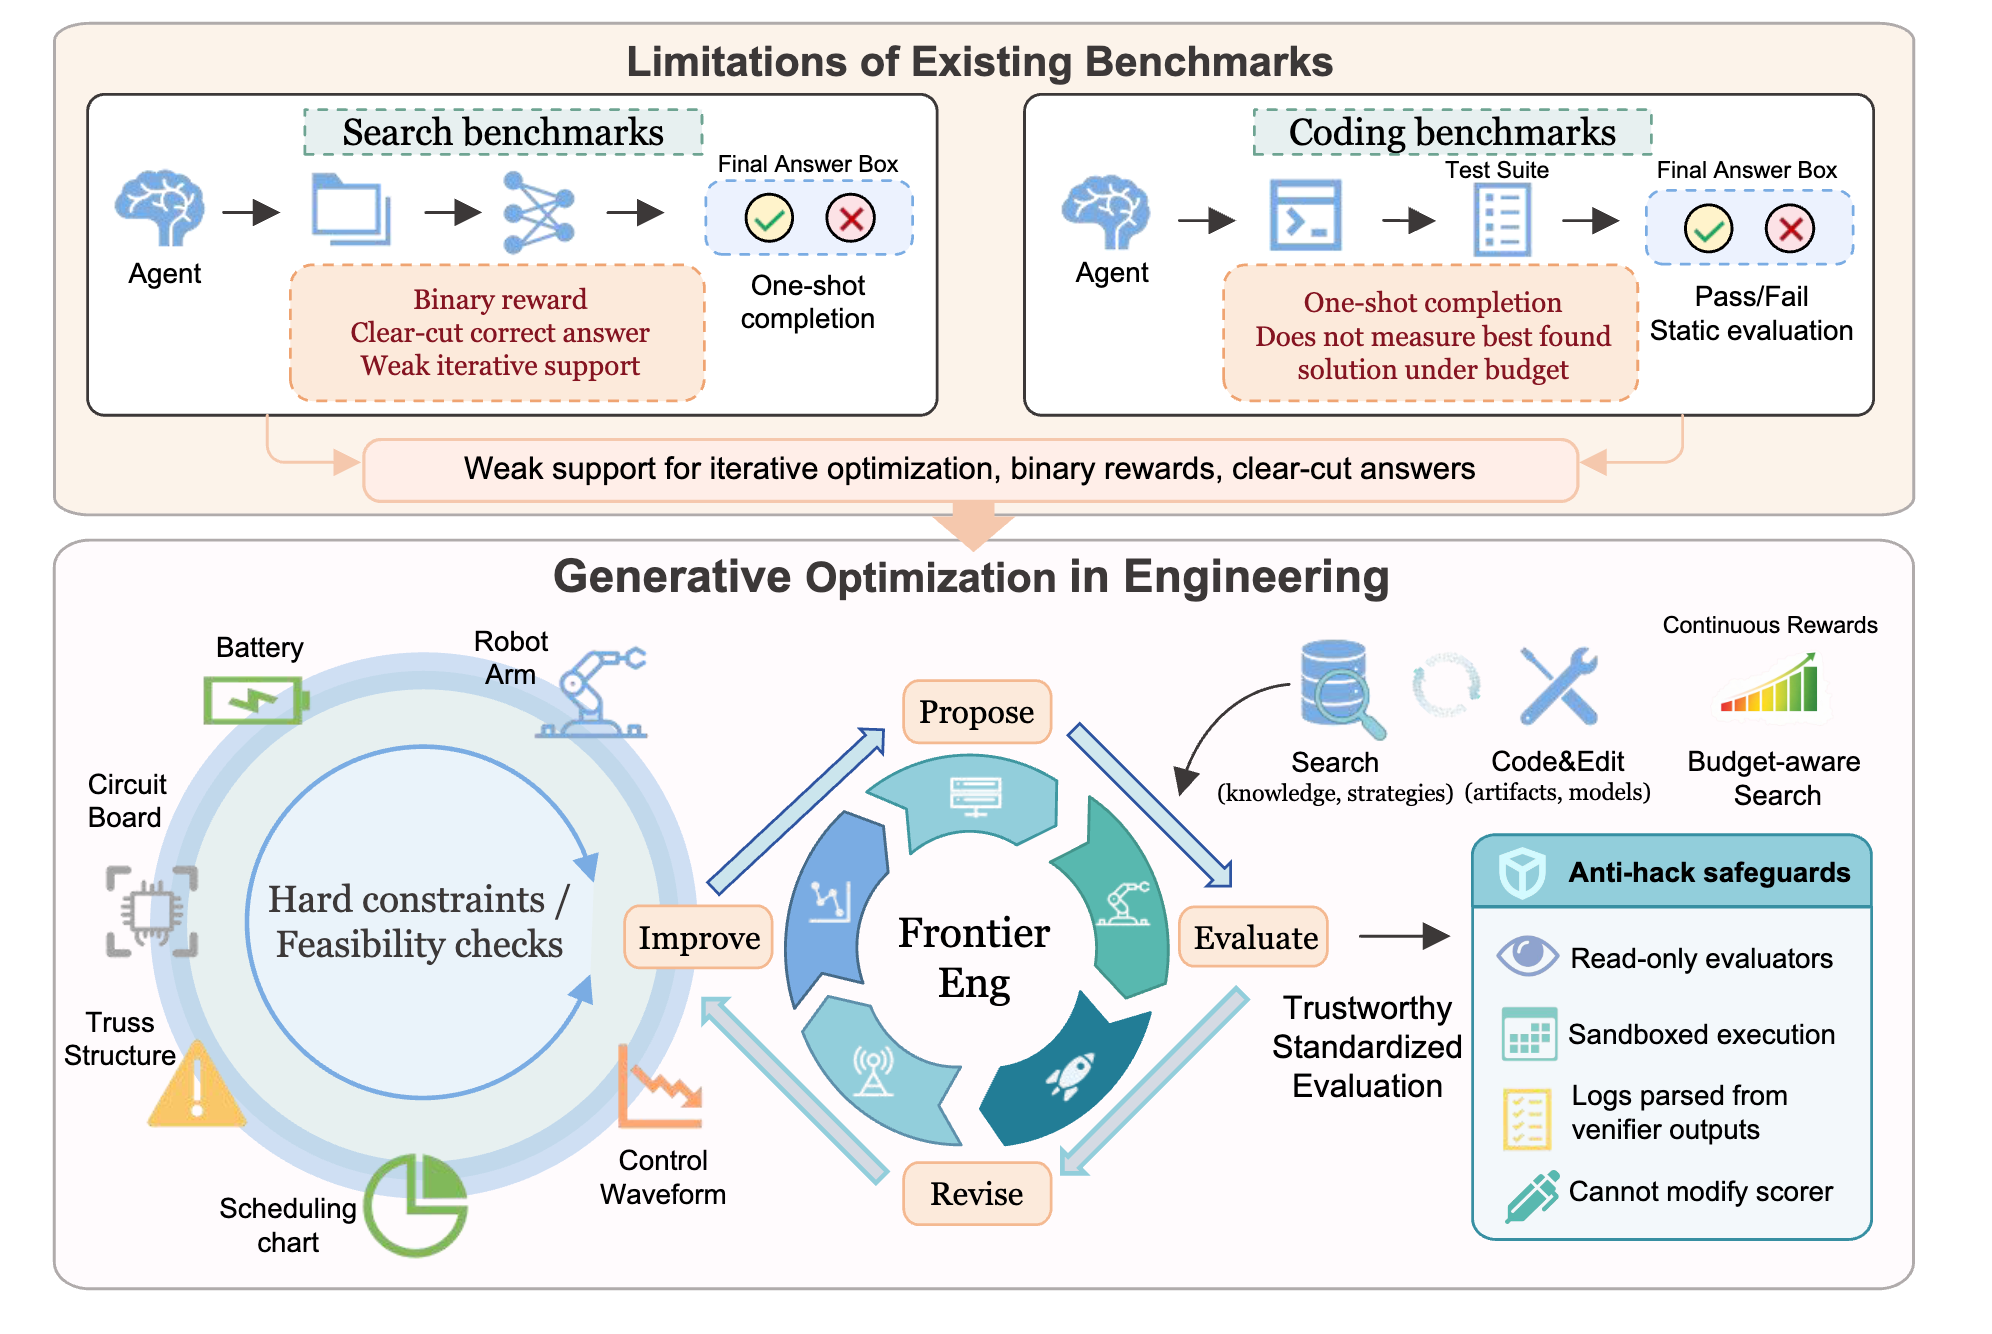
Frontier-Engineering
Open engineering benchmark: agents on optimization across aerospace scheduling, EDA, quantum circuits, fiber optics, battery control, and more. 47 tasks across five engineering categories.