Visual Cipher Bench
Can a coding agent discover the rules hidden in an image, and reason all the way to an answer?
Navers Lab · Einsia.AI · Tsinghua University · 2026
- 40
- original visual puzzles
- 29
- configurations of 8 models
- 26.7%
- best accuracy, GPT-6 Astra
- 3,480
- graded runs, 3 per task
Overview
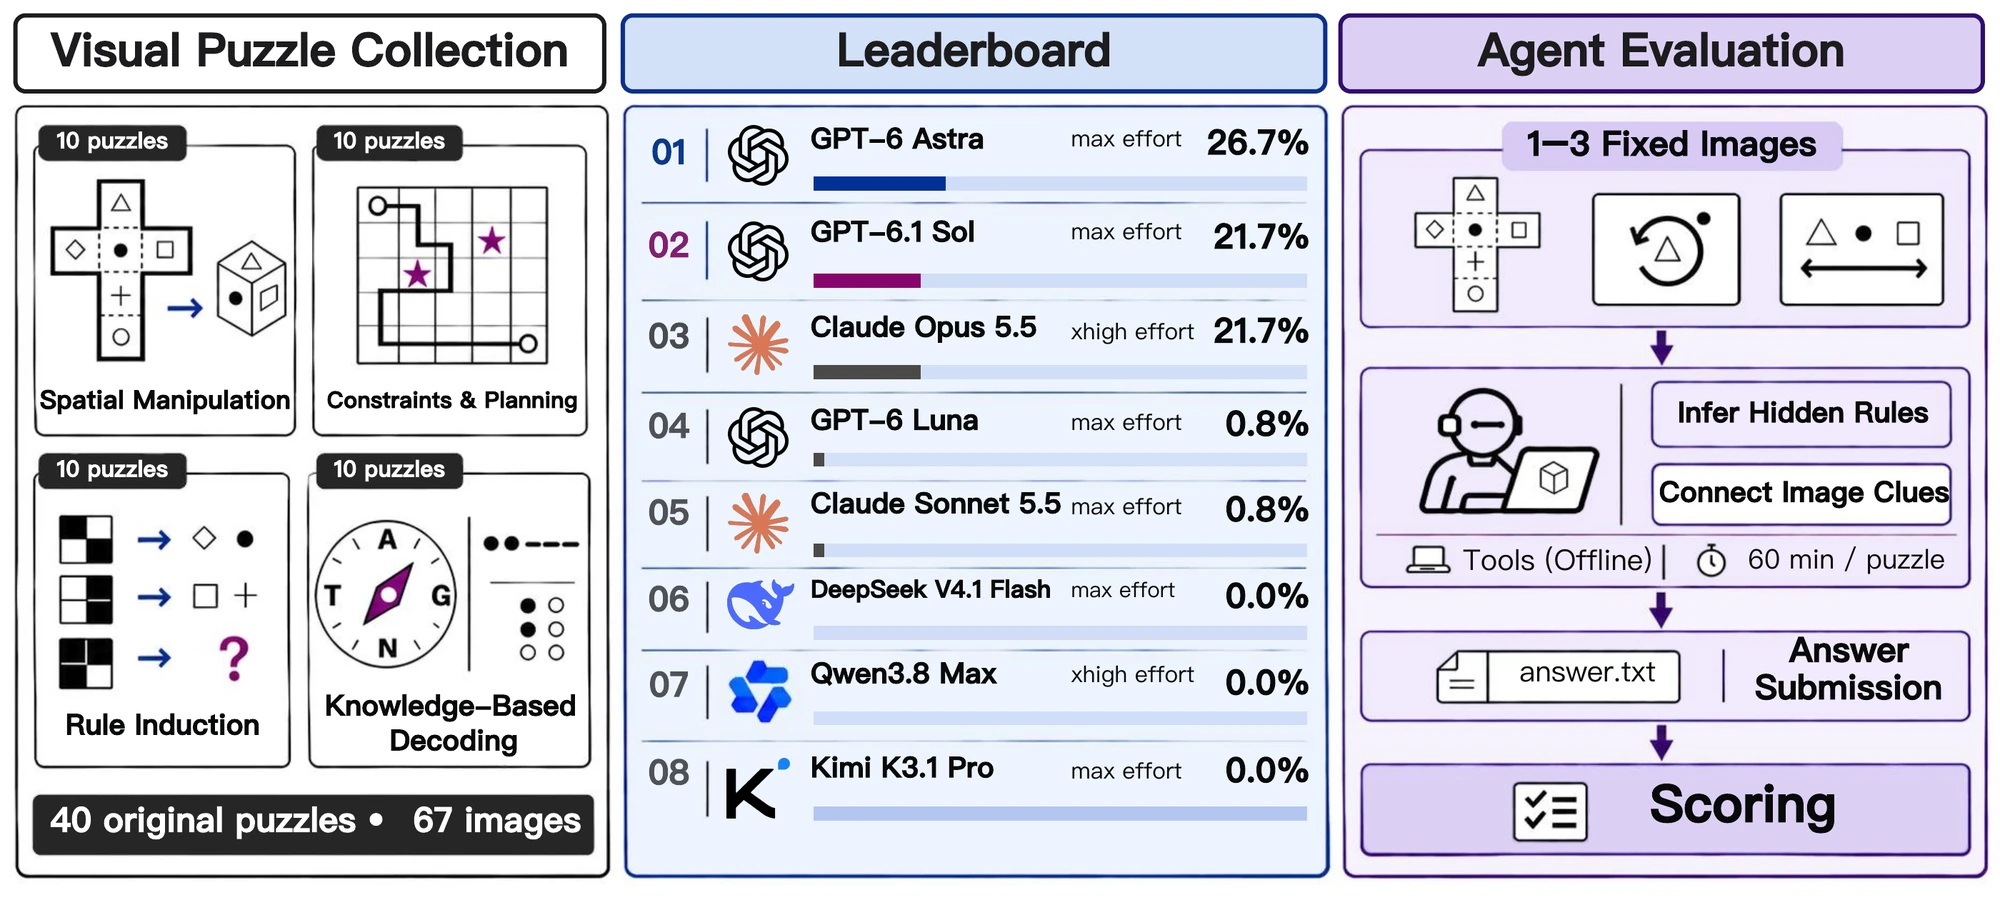
Coding agents usually work from a written spec and a test suite. Here each task is just one to three black-and-white drawings and an instruction to submit an answer, so the agent has to work out the rule itself and carry it through to a final answer. The 40 puzzles cover four categories: spatial manipulation, logic and planning, rule induction, and knowledge-based decoding.
Leaderboard
Eight models at one or more reasoning-effort levels make 29 configurations. GPT-6 Astra at max effort leads at 26.7%, with GPT-6.1 Sol and Claude Opus 5.5 at 21.7%; the other five models stay below 1%.
- P1 Spatial
- 20.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 30.0%
- P2 Logic
- 6.7%
- P3 Rule induction
- 3.3%
- P4 Decoding
- 6.7%
- P1 Spatial
- 63.3%
- P2 Logic
- 10.0%
- P3 Rule induction
- 3.3%
- P4 Decoding
- 10.0%
- P1 Spatial
- 66.7%
- P2 Logic
- 6.7%
- P3 Rule induction
- 3.3%
- P4 Decoding
- 13.3%
- P1 Spatial
- 80.0%
- P2 Logic
- 13.3%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 13.3%
 GPT-6 Astra
- P1 Spatial
- 16.7%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 3.3%
- P1 Spatial
- 26.7%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 6.7%
- P1 Spatial
- 36.7%
- P2 Logic
- 3.3%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 6.7%
- P1 Spatial
- 53.3%
- P2 Logic
- 6.7%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 3.3%
- P1 Spatial
- 60.0%
- P2 Logic
- 10.0%
- P3 Rule induction
- 3.3%
- P4 Decoding
- 13.3%
GPT-6.1 Sol - P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 33.3%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 40.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 3.3%
- P1 Spatial
- 70.0%
- P2 Logic
- 6.7%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 10.0%
- P1 Spatial
- 56.7%
- P2 Logic
- 6.7%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 6.7%
 Claude Opus 5.5
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 3.3%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
GPT-6 Luna - P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 3.3%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
- P1 Spatial
- 3.3%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
Claude Sonnet 5.5 - P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
 DeepSeek V4.1 Flash
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
 Qwen 3.8 Max
- P1 Spatial
- 0.0%
- P2 Logic
- 0.0%
- P3 Rule induction
- 0.0%
- P4 Decoding
- 0.0%
 Kimi K3.1 Pro
Show all 29 configurations by category Hide full results
| Model | Effort | Overall (%) | Spatial | Logic | Rule induction | Decoding |
|---|---|---|---|---|---|---|
| GPT-6 Astra | max | 26.7 | 80.0 | 13.3 | 0.0 | 13.3 |
| xhigh | 22.5 | 66.7 | 6.7 | 3.3 | 13.3 | |
| high | 21.7 | 63.3 | 10.0 | 3.3 | 10.0 | |
| medium | 11.7 | 30.0 | 6.7 | 3.3 | 6.7 | |
| low | 5.0 | 20.0 | 0.0 | 0.0 | 0.0 | |
| GPT-6.1 Sol | max | 21.7 | 60.0 | 10.0 | 3.3 | 13.3 |
| xhigh | 15.8 | 53.3 | 6.7 | 0.0 | 3.3 | |
| high | 11.7 | 36.7 | 3.3 | 0.0 | 6.7 | |
| medium | 8.3 | 26.7 | 0.0 | 0.0 | 6.7 | |
| low | 5.0 | 16.7 | 0.0 | 0.0 | 3.3 | |
| Claude Opus 5.5 | max | 17.5 | 56.7 | 6.7 | 0.0 | 6.7 |
| xhigh | 21.7 | 70.0 | 6.7 | 0.0 | 10.0 | |
| high | 10.8 | 40.0 | 0.0 | 0.0 | 3.3 | |
| medium | 8.3 | 33.3 | 0.0 | 0.0 | 0.0 | |
| low | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| GPT-6 Luna | max | 0.8 | 3.3 | 0.0 | 0.0 | 0.0 |
| xhigh | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| high | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| medium | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| low | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| none | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| Claude Sonnet 5.5 | max | 0.8 | 3.3 | 0.0 | 0.0 | 0.0 |
| xhigh | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| high | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| medium | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | |
| low | 0.8 | 0.0 | 0.0 | 3.3 | 0.0 | |
| DeepSeek V4.1 Flash | max | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| Qwen 3.8 Max | xhigh | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| Kimi K3.1 Pro | max | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
Key findings
01
Rule discovery is the bottleneck
Across all 3,480 runs, agents reach 22.8% on spatial puzzles, where the operation is drawn in the images. When a rule must be induced from a few examples, they almost never succeed: 5 correct answers in 870 attempts.
02
Naming the mechanism changes the outcome
On ten tasks, one sentence naming the state representation and update rule, with no intermediate states and no answer, lifts accuracy from 7.8% to 55.6%. Rule induction gains the most, from 3.7% to 81.5%.
03
Failures leave the evidence unused
- Wrong answers: unchecked rules
- Agents stop at a rule that explains some examples and answer without testing it on the rest.
- Timeouts: search without pruning
- They enumerate generic rule families or every combination of states instead of using the puzzle's constraints.
Out of 90 runs on the ten hinted tasks, timeouts fall from 51 to 18 within the same 60 minutes: the problem is a search the evidence never narrowed, not a lack of time.
Evaluation setup
Every configuration attempts every task three times under the same conditions. The agent can inspect the images and run code, but gets no feedback on correctness until its final answer is scored.
- 60 min
- per run
- 2 CPUs
- 4 GB memory, no GPU
- Offline
- network disabled
- 3 runs
- per task, 3,480 in total
Every task gives the agent the same instruction:
Solve this visual reasoning puzzle: examine all images in /app/images/ and write the single final answer to /work/answer.txt. Write only the answer itself, with no quotes, punctuation, or explanation.
- Agents
- Codex CLI for GPT models and Claude Code CLI for all others, run through Harbor
- Environment
- Python 3.12 with NumPy and Pillow; the puzzle images are read-only
- Scoring
- Exact match on answer.txt after fixed normalization, graded in a separate container
- Scored as zero
- Timeouts, missing answers, symbolic links and answers over 4 KB
Citation
@article{hong2026visualcipherbench,
  title   = {Visual Cipher Bench: Benchmarking LLM Agents on Long-Horizon Visual Reasoning},
  author  = {Deyao Hong and Jiayi Jiang and Yuchun Chen and Yixuan Shi and Wenyi Li
             and Zheng Jiang and Chengxing Xie and Mingyu Su and Qingle Liu and Mingju Gao
             and Yizhe Chi and Youjie Zheng and Calvin Xiao and Kaisen Yang
             and Huan-ang Gao},
  journal = {arXiv preprint arXiv:2611.16861},
  year    = {2026}
}